

By
Associate Professor at aivancity
Director of the MSc Intelligences Artificielles Génératives & Agentiques
Zainab Assaghir
Full Professor
Faculty of Sciences, Lebanese University
Libraries of educational prompts are multiplying, but they describe what we ask generative AI to produce, rarely the pedagogical function of that request. Our study proposes a taxonomy of five pedagogical functions of prompts and shows that it can be applied reliably by two raters. It also shows that it is difficult to infer, from the text of a prompt alone, the level of cognitive complexity it will engage.
Generative artificial intelligence is becoming embedded in educational practice, to the point that UNESCO and the OECD now devote recommendation frameworks to it (Miao and Holmes, 2023; OECD, 2026). Teachers use it to prepare lessons, design activities or produce course materials; students use it to get explanations, practice or receive feedback on their work. In all these uses, the interaction goes through a prompt, that is, the instruction written for a generative AI model.
Behind this diversity of uses lies a more fundamental question: what does a prompt actually do pedagogically?
Does it simply ask the AI to produce an answer, does it guide the learner step by step, does it require them to argue a position, or does it lead them to evaluate their own reasoning?
This is the question addressed by our study From Engineering to Pedagogy: A Functional Taxonomy for Teacher and Student-Facing Educational Prompting, published in the proceedings of the EC-TEL 2026 conference (Yaacoub and Assaghir, 2027). In it, we propose classifying educational prompts not only according to the task they ask to be performed, but according to the pedagogical function they seek to fulfill.
After calibration, two raters applying this classification to 50 unseen prompts achieve high agreement (88%, κ = 0.80). However, the text of a prompt, taken in isolation, does not reliably reveal the level of cognitive complexity it will actually engage. The corpora, the coding scheme and the annotation workbook are available in open access on the OSF platform.
Why look beyond “prompt engineering”?
Libraries of educational prompts are growing rapidly. Recent literature reviews highlight the rise of large language models in education, the heterogeneity of prompt-writing practices and the lack of a shared analytical framework (Chen et al., 2024; Shi et al., 2026). These libraries are most often organized around the task to be performed: preparing a lesson, generating a quiz, creating an assessment rubric, explaining a concept.
This organization is useful in practice, but it says little about the intended pedagogical mechanism and makes it difficult to compare prompts from one context to another.
Two prompts that appear to request the same task can in fact organize the cognitive work very differently.
One provides an answer directly; another guides the user step by step; a third asks them to justify their reasoning, consider a counterargument or evaluate their own work.
The question is therefore no longer only what we ask the AI to produce, but how the prompt organizes the cognitive activity of the teacher or the learner.
This distinction matters in education, where the quality of an interaction with AI depends not only on the quality of the generated response, but also on what the user is led to do themselves.
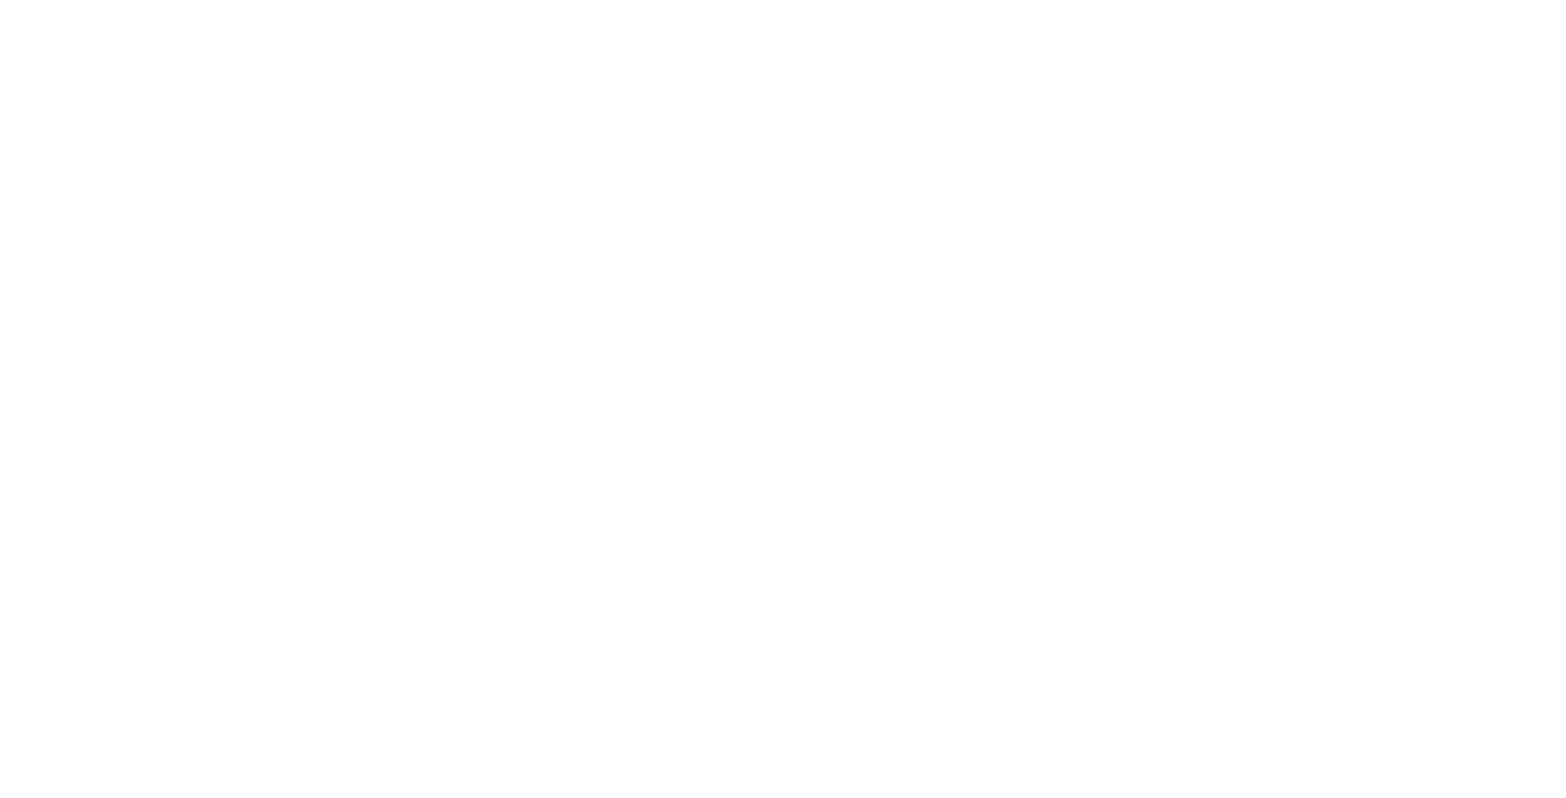
Five pedagogical functions for analyzing prompts
Our taxonomy draws on scaffolding theory (Wood, Bruner and Ross, 1976) and on research into self-regulated learning (Zimmerman, 2002). It distinguishes five functions, and each prompt receives a single code: that of its dominant function. The English names given in parentheses are those of the published taxonomy.
1. Scaffolding: guiding without reasoning in the learner’s place
The Scaffolding category groups together prompts that offer steps, templates, hints or forms of gradual support.
The principle is to provide enough structure to let the user make progress, while leaving them responsible for the core reasoning.
One prompt in our corpus, for example, asks the AI to build an educational simulation run by a “game master” who structures how the activity unfolds.
The boundary with the other categories requires precision. A series of questions is not automatically Socratic: if the questions mainly serve to gather the information needed to complete a task, they fall under scaffolding. This is one of the decision rules established during calibration.
2. Socratic: asking questions rather than giving the answer
In this category, the AI is explicitly instructed to ask questions that elicit, clarify or challenge the user’s reasoning, and to withhold the direct answer.
The goal is not to gather information gradually, but to use questioning to exercise reasoning.
This definition avoids labeling as “Socratic” any dialogue in which the AI asks several successive questions.
3. Cognitive Enforcement: imposing operations that require deeper thinking
This category refers to prompts that introduce constraints requiring the user to engage specific cognitive operations: critique, synthesis, counterargument, trade-off analysis or rubric-based evaluation.
The aim is to move beyond superficial completion of a task.
Asking for a text to be produced in several steps is not enough; asking the user to examine an opposing argument, compare options against explicit criteria or critique a piece of work using a rubric introduces an additional constraint. One prompt in our corpus, for instance, asks the AI to critique a lesson plan using a rubric based on Universal Design for Learning.
4. Metacognitive: observing one’s own reasoning
This function covers prompts that make explicit the operations of planning, monitoring, self-assessment, error analysis or revision against defined criteria.
The presence of reflective vocabulary is not enough: a concrete action of checking one’s own work must be required, for example a checklist that the learner applies to their output in a tutoring exercise.
This category relates to the mechanisms of self-regulated learning: planning one’s activity, monitoring one’s progress and evaluating the outcome (Zimmerman, 2002).
5. Other/Unclear: producing without an identifiable pedagogical protocol
This last category mainly groups together prompts that request the generation of an artifact, such as an assessment rubric or course materials, without an identifiable pedagogical protocol.
However, producing teaching material is not automatically classified in this category: if the prompt includes a pedagogical sequence, an inquiry mechanism or another identifiable function, that function takes precedence.
How was this taxonomy tested?
The study was conducted in two stages.
An initial development corpus of 50 English-language prompts was assembled from four public libraries accessed on February 9, 2026: More Useful Things (11 prompts), Wharton Interactive (6), Microsoft prompts-for-edu (6) and AI for Education (27). The prompts were chosen to cover the range of categories offered by each library.
This corpus reflected a feature of today’s public libraries: it was overwhelmingly aimed at teachers (46 prompts out of 50).
The two authors of the study, both researchers in educational technology, independently coded each prompt along two dimensions.
The first was its dominant pedagogical function.
The second was based on the SOLO (Structure of the Observed Learning Outcome) taxonomy, which classifies the complexity of a response into successive levels: unistructural, multistructural, relational and extended abstract (Biggs and Collis, 1982; Yaacoub et al., 2025). It was used here in an exploratory way, to check whether the targeted level of cognitive complexity could be inferred from the text of a prompt alone.
To measure inter-rater consistency, the study uses percent agreement and Cohen’s kappa (κ). The latter estimates agreement between two raters while accounting for the share of agreement that could occur by chance. According to the most common interpretation scale, a κ between 0.41 and 0.60 corresponds to moderate agreement, between 0.61 and 0.80 to substantial agreement, and above that to almost perfect agreement (Landis and Koch, 1977). These thresholds remain conventional and vary from author to author (McHugh, 2012).
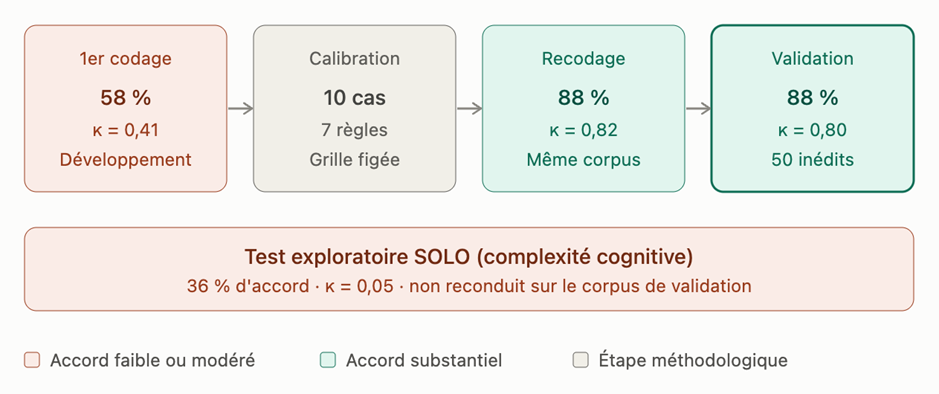
An imperfect first classification, then clear improvement after calibration
In the first coding round of the development corpus, classification by pedagogical function reached 58% agreement, with a κ of 0.41 (95% confidence interval: [0.24, 0.57]), i.e., moderate agreement.
Disagreements were concentrated on three boundaries: Scaffolding/Other (4 cases), Scaffolding/Socratic (3) and Scaffolding/Metacognitive (3).
This result is instructive in itself: categories do not become reliable simply because they have been defined; their boundaries must be precise enough for several raters to apply them consistently.
A calibration session therefore focused on ten cases with strong disagreement. It resulted in seven decision rules, addressing in particular the distinction between Socratic questioning and scaffolding, and the treatment of prompts devoted to generating artifacts.
The coding scheme was then frozen. A new coding of the same corpus then reached 88% agreement and a κ of 0.82 ([0.67, 0.94]).
This improvement, obtained on prompts that had already been discussed, was not enough, however, to demonstrate that the rules worked on new prompts.
Validation on 50 unseen prompts
The taxonomy was therefore evaluated on a second corpus of 50 prompts, assembled after the coding scheme was finalized and excluding any prompt from the development corpus.
This corpus was deliberately balanced between 25 prompts aimed at teachers and 25 prompts aimed at students, drawn from Microsoft prompts-for-edu (6 and 8) and AI for Education (19 and 17).
Only the pedagogical function was coded, in two independent blind passes using the frozen scheme, with no discussion between passes before agreement was calculated.
The main result is 88% agreement, with κ = 0.80 and a 95% confidence interval of [0.64, 0.93].
The results are similar for both audiences: 92% agreement and κ = 0.81 for prompts aimed at teachers, 84% and κ = 0.78 for those aimed at students.
However, these two subsamples contain only 25 prompts each: these figures remain indicative, and the gap between them was not statistically tested.
Under the conditions of this study, these results indicate that the taxonomy retains substantial reliability on prompts not used during its construction, whether they are aimed at teachers or students. Not all boundaries disappear, however. The six remaining disagreements involve Scaffolding/Cognitive Enforcement (2), Scaffolding/Other (2), Scaffolding/Socratic (1) and Scaffolding/Metacognitive (1). All of them involve scaffolding, which makes it, in our corpus, the category whose boundaries with the other functions remain the hardest to draw.
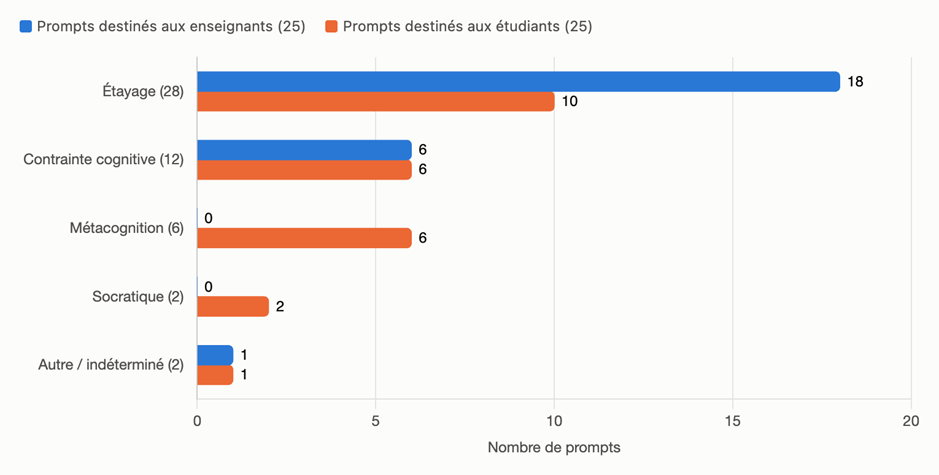
Not all functions are equally represented
In the validation corpus, scaffolding is the dominant function, with 28 prompts out of 50: 18 aimed at teachers and 10 at students.
Cognitive enforcement accounts for 12 prompts, split evenly between the two audiences.
The six metacognitive prompts, on the other hand, are all aimed at students, as are the two Socratic prompts. The Other/Unclear category includes two prompts.
This distribution should be interpreted with caution. The corpus was deliberately built with equal shares for the two audiences, from only two libraries: its distribution describes this sample, not the frequency of these functions across educational prompts as a whole. It nevertheless suggests a hypothesis to be tested on larger corpora: certain functions, such as metacognition and Socratic questioning, may be more prevalent in prompts aimed directly at learners.
An instructive negative result: the limits of SOLO based on the prompt alone
One of the study’s important findings concerns not what worked, but what did not work reliably.
In the first coding round, using SOLO to infer cognitive complexity from the text of the prompts produced only 36% inter-rater agreement, with κ = 0.05, a level close to chance.
Ordinal weighting, which accounts for the distance between levels, did not improve the result. Given this weakness, SOLO coding was not repeated on the validation corpus.
The gap with the pedagogical function is explained by the nature of what is being coded. The functions in our taxonomy often correspond to mechanisms explicitly stated in the text: “proceed step by step,” “use a rubric,” “propose a counterargument,” “check your work.”
Cognitive complexity, by contrast, requires inferring the level of understanding actually demanded, information that the prompt, taken in isolation, rarely provides.
The same text can produce different interactions depending on the context, the user, the model used and the successive responses generated over the course of the exchange.
This result calls for methodological caution: to analyze cognitive complexity with a framework such as SOLO, the relevant unit of analysis may be the prompt-response pair, or even the full interaction, rather than the prompt alone.
Designing an educational prompt also means deciding where the cognitive effort lies
This taxonomy can serve as an analytical lens, but also as a design tool. The recommendations that follow do not derive from the study’s results, since it does not observe learning: they derive from its theoretical framework and align with existing recommendations on the responsible use of generative AI in education (Miao and Holmes, 2023; OECD, 2026).
First, they encourage avoiding a systematic “answer-first” logic, in which the AI immediately provides the expected result.
Scaffolding and Socratic questioning, by contrast, can preserve a degree of productive effort by requiring intermediate steps or justifications.
Cognitive enforcement makes it possible to explicitly introduce operations of critique, synthesis, counterargument or evaluation.
Finally, metacognitive prompts can make the steps of planning, monitoring and self-assessment visible.
In courses and activities that involve writing code, I often observe the same reflex: the student pastes their code and error message, then asks the AI to fix it. The prompt gets an answer, but the diagnosis escapes them. So I reworded the instruction I give them: the assistant must not provide corrected code, but ask one question at a time to lead the student to form a hypothesis about the source of the error, and then to test it. The task stays the same. What changes is who carries the reasoning.
No category is inherently superior to the others, however. The relevant function depends on the learning objective, the context, the learner and the way the interaction with AI is actually implemented.
These design choices are not merely technical. Deciding how much of the reasoning to hand over to the AI also means deciding how much autonomy to leave to the learner: a prompt that systematically provides the answer can relieve them of that reasoning, while a prompt that withholds it leaves them responsible for it. This decision calls for transparency, because a student who does not understand why the assistant refuses to give them the solution may perceive this restraint as a limitation of the tool rather than as a pedagogical choice. It also raises a question of inclusion: the prompts studied come from English-language libraries designed in specific educational contexts, and transferring them to French-speaking or multilingual learners is not straightforward. Finally, these prompts run on models whose behavior changes from version to version; a pedagogical function carefully built into a prompt therefore also depends on technical choices beyond the teacher’s control.
What this study shows, and what it cannot yet conclude
The study shows that, after calibration, the five proposed functions can be distinguished with substantial reliability on the validation corpus studied.
It does not, however, demonstrate that one type of prompt produces better learning than another.
The analysis focuses on the text of the prompts: it does not observe the interactions that follow, the models’ responses, the work produced by learners or their learning outcomes.
Yet the pedagogical function embedded in a prompt can shift when it is implemented in a real-world setting.
A next research step is therefore to link prompt categories to observed interactions and outcomes: for example, testing whether scaffolding or Socratic prompts elicit more productive struggle, the effort through which learners must search, reason and justify, than prompts geared toward directly generating a result.
Several limitations must also be taken into account.
Both corpora are small and come from English-language public libraries; the results therefore cannot be generalized without caution to multilingual environments, less structured libraries or real-world tutoring situations.
Moreover, the development and validation corpora come from the same broad families of sources. Finally, validation was carried out in two independent passes with the same frozen scheme, not by a new team of annotators. It should therefore be read as out-of-sample stability of the coding scheme, rather than as full proof that it generalizes to other teams.
From the prompt as instruction to the prompt as pedagogical design
The development of generative AI in education raises a question that goes beyond mastering prompt engineering alone, that is, the art of writing effective instructions for a model.
An educational prompt is not only an instruction meant to obtain better output: it also determines who reasons, at what point, under what constraints and with what degree of autonomy.
The proposed taxonomy provides a vocabulary for analyzing these differences.
It is only a first step. It remains to be seen how these functions play out in real interactions and what effects they have on learning processes and outcomes.
The challenge then shifts: it is no longer only about writing prompts that help the AI respond better, but about designing interactions in which AI supports learning without absorbing the cognitive work that gives it its value.
References
[1] Biggs, J. B., and Collis, K. F. (1982). Evaluating the Quality of Learning: The SOLO Taxonomy (Structure of the Observed Learning Outcome). New York: Academic Press.
[2] Chen, E., et al. (2024). A Systematic Review on Prompt Engineering in LLMs for K-12 STEM Education. arXiv:2410.11123. View the preprint
[3] Landis, J. R., and Koch, G. G. (1977). The Measurement of Observer Agreement for Categorical Data. Biometrics, 33(1), 159-174.
[4] McHugh, M. L. (2012). Interrater Reliability: The Kappa Statistic. Biochemia Medica, 22(3), 276-282. View the scientific article
[5] Miao, F., and Holmes, W. (2023). Guidance for Generative AI in Education and Research. Paris: UNESCO. View the guide
[6] OECD (2026). OECD Digital Education Outlook 2026. Paris: OECD Publishing. View the report
[7] Shi, Y., Yu, K., Dong, Y., and Chen, F. (2026). Large Language Models in Education: A Systematic Review. Computers and Education: Artificial Intelligence, 10, 100529. View the study
[8] Wood, D., Bruner, J. S., and Ross, G. (1976). The Role of Tutoring in Problem Solving. Journal of Child Psychology and Psychiatry, 17(2), 89-100. View the scientific article
[9] Yaacoub, A., and Assaghir, Z. (2027). From Engineering to Pedagogy: A Functional Taxonomy for Teacher and Student-Facing Educational Prompting. In J. Weidlich et al. (Eds.), Mindful TEL: Learning Technologies Shaped with Intention. EC-TEL 2026. Lecture Notes in Computer Science, vol. 16906, pp. 255-260. Cham: Springer. View the publication
[10] Yaacoub, A., Assaghir, Z., and Da-Rugna, J. (2025). Cognitive Depth Enhancement in AI-Driven Educational Tools via SOLO Taxonomy. In ACR’25, LNNS 1346, pp. 14-25. Springer. View the publication
[11] Open Science Framework (OSF). Matériaux ouverts : corpus, grille de codage et classeur d’annotation. View the research materials