

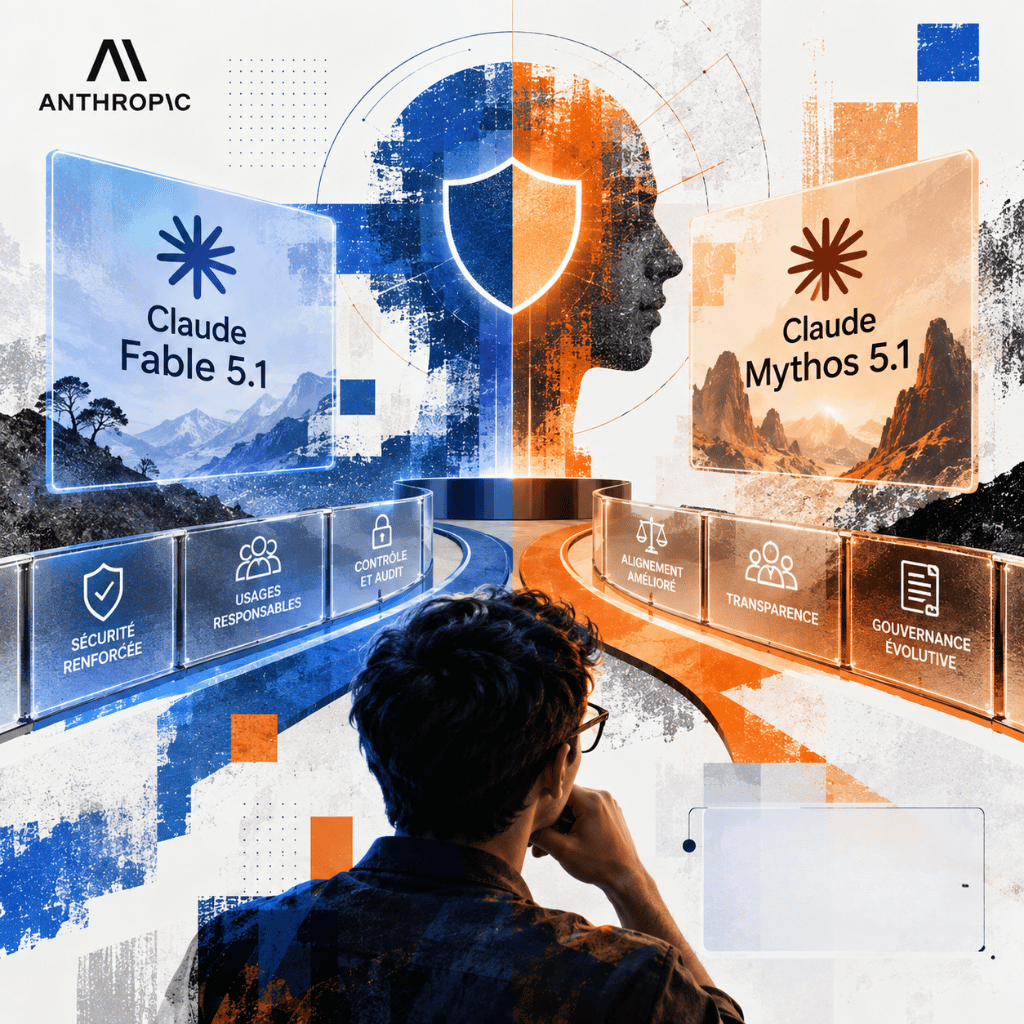
Presented by Anthropic on September 1, 2026, Claude Fable 5.1 and Claude Mythos 5.1 are built on the same model, but they do not unlock the same sensitive uses. Fable is widely available with strengthened safeguards, while Mythos is reserved for vetted professionals in cybersecurity and the life sciences. The most important innovation, then, is not two levels of intelligence but a distribution of capabilities based on identity, context of use and risk.
What Anthropic launched
Anthropic describes Claude Fable 5.1 as a model built for demanding reasoning and long-running agentic work. It accepts text and images as input, produces text, uses tools and handles a context of up to one million tokens. The announced maximum output reaches 128,000 tokens. Adaptive reasoning is always on, and the effort level can be adjusted during a conversation.[1][2]
Claude Mythos 5.1 shares the same capabilities, the same specifications and the same pricing. The difference lies in safeguards and access. Fable 5.1 is available to all Claude API customers and on several partner platforms. Mythos 5.1 is offered through Project Glasswing and Anthropic’s trusted access programs. At launch, access to sensitive capabilities was limited to a set of vetted US organizations, with an international expansion announced but no firm timeline.[1][2]
This distinction corrects a misleading reading of the launch. Mythos is not a second, inherently more powerful model. Anthropic states that Fable 5.1 and Mythos 5.1 are the same underlying model. The gaps observed on certain tasks therefore stem mainly from the safety policies that accept, refuse or redirect a request, as well as from the evaluation environment.[1][4]
What actually changes
The first change concerns long tasks. Anthropic is targeting agentic coding, multi-step research and the production of documents, spreadsheets and presentations. The model can analyze a goal, call a tool, check a result, correct a step and keep working. This loop already existed in other systems. Fable 5.1 mainly seeks to make it more reliable over longer trajectories and in complex professional environments.[2]
The second change is economic. Base prices remain set at $10 per million input tokens and $50 per million output tokens. Cache reads, however, drop to $0.25 per million tokens, a quarter of the rate charged for Fable 5. Anthropic estimates that this reduction cuts the cost of typical workloads by about 25% and that of highly agentic tasks by up to about 45%. These percentages are vendor estimates based on four weeks of observed usage in August 2026, not a guarantee that applies to every deployment.[1][2]
The third change concerns the precision of safeguards. Anthropic now allows Fable 5.1 to search for software vulnerabilities in a defensive context and reports about 60% fewer cyber interventions per Claude Code session than with Fable 5’s initial protections. Penetration testing, exploit generation and binary analysis are still redirected to other models. In biology, the company says protections trigger 85% less often on benign requests about basic biology or health, while advanced research remains restricted.[1]


MSc AI Governance, Risk & Compliance
The Bac+6 program that trains legal professionals to understand AI and data technologies so they can master their governance, risks and compliance.
How differentiated access works
The model processes a request within a broader system that includes risk classifiers, usage policies, routing rules, tool permissions and account characteristics. The same technical capability can therefore produce three different outcomes: a direct answer, a redirection to a model deemed more suitable, or a refusal. In sensitive domains, verified identity and membership in an authorized program can change the policy that applies.
This architecture brings agentic AI closer to a privilege-based system. In IT infrastructure, two users can run the same software with different rights. Here, Fable 5.1 and Mythos 5.1 share the engine, but the governance layer determines which requests can be processed and which actions the environment allows. Identity, however, is only a signal of trust. It guarantees neither the legitimacy of each request nor the safety of each trajectory.
Enterprise Frontier Safeguards adds a layer designed for businesses. Anthropic says data and logs can remain within cloud infrastructure controlled by the customer, with human review performed by the customer by default. The vendor presents this setup as compatible with a level of confidentiality equivalent to a zero-retention policy, while keeping automated abuse-detection mechanisms in place. Rollout is gradual. Absent express authorization, the documentation specifies a thirty-day retention period for Fable 5.1 and Mythos 5.1.[2][5]
Technology Framework
| Capability or constraint | What to understand |
|---|---|
| Common foundation | Fable 5.1 and Mythos 5.1 use the same model. Access policies and safeguards create the operational difference. |
| Context | One million tokens announced, with no guarantee that every piece of information in such a long context is used with the same precision. |
| Output | Up to 128,000 tokens. Long outputs and trajectories increase cost, duration and the surface for errors. |
| Reasoning | Adaptive reasoning always on, with an adjustable effort parameter. Maximum effort consumes more compute. |
| Modalities | Text and images as input, text as output. Actions depend on the tools connected to the model. |
| Tools | Coding, terminal, search, documents and interfaces depending on the product. Forced tool calls are not supported on these models. |
| API pricing | $10 per million input tokens, $50 per million output tokens and $0.25 for cache reads. |
| Sensitive access | Mythos 5.1 is reserved for trusted programs in cyber defense and the life sciences. |
| Data | Thirty-day retention by default, unless specifically authorized otherwise. EFS provides for storage and review under the customer’s control. |
Why this architecture matters for organizations
For a business, the distinction between capability and permission is more useful than a general ranking of models. An agent may know how to modify a software repository, consult a customer file or launch an analysis without needing to hold those rights permanently. Choosing a model therefore does not replace the principle of least privilege, human approvals, logging or the separation between test and production environments.
The lower cache cost may make some long workflows more accessible. An agent that rereads the same instructions, documents and intermediate results pays less for that part of the context. The real gain, however, depends on how the task is structured. A job that reuses a lot of context will benefit more from caching than a series of independent requests. The cost per job must also factor in tool calls, infrastructure, retries and human review time.
The same reasoning applies to professional roles. Development, security, research and analytics teams can delegate longer subtasks, but they must define success criteria, verify sources and know when to stop a trajectory. Professional expertise remains necessary to tell a plausible result from an acceptable one, especially when the model writes code, interprets an experiment or acts on a real system.
In the life sciences, Anthropic reports results that deserve attention. Mythos 5.1 reportedly achieved a success rate close to 50% in designing binding proteins tested against twelve targets, after external experimental validation. The model also reportedly sped up seven computational biology models by as much as 2.5 times, with estimated savings of 30% to 60% on certain computations. These are case studies announced by the vendor. They do not demonstrate a general capability for autonomous scientific discovery.[1]
MSc Generative AI
and Agentic AI
Become an expert in generative and agentic AI: LLMs, transformers, enterprise deployment. Silicon Valley learning trip included. RNCP Level 7 certification (Bac+6).
What the results actually support
The tables published by Anthropic show Fable 5.1 improving on agentic coding, assisted scientific research and professional workflows. They do not prove general superiority. Scores depend on the effort level, the harness, the tools, the safeguards and the scoring method. The gap between Fable and Mythos on Terminal-Bench 4.0 shows precisely that safety policy can change observed performance even when the base model is identical.[1]
| Evaluation | Fable 5 | Fable 5.1 | Cautious reading |
|---|---|---|---|
| Terminal-Bench Science 0.1 | 24.7% | 52.6% | Significant gain, with a reported standard error of 3.5 to 4.5 points and a setup different from the public leaderboard. |
| Terminal-Bench 4.0 | 42.0% | 55.8% | Mythos 5.1 reaches 60.9%. The gap does not reflect a different model but, among other things, different safeguards. |
| AutomationBench | 17.1% | 31.4% | The published score uses Opus 5 as a fallback on about 40% of the 657 tasks. The reported cost does not fully cover this combination. |
| OSWorld 2.0 | 36.1% strict | 41.7% strict | The partial score reaches 77.9%, but it should not be confused with the strict task completion rate. |
| CursorBench 3.2.0 | 70.5% | 73.4% | Cursor’s result at maximum effort. A 2.9-point gap does not describe every project or every cost. |
AutomationBench calls for particular caution. Zapier’s leaderboard specifies that steps refused by Fable 5.1 were taken over by Opus 5 and that this fallback model stepped in on about 260 of the 657 tasks. The 31.4% score therefore measures a combined system, while the published cost per task covers only Fable 5.1. Comparing this figure with a model used on its own without reproducing the routing would be misleading.[6]
OSWorld 2.0 distinguishes between partial score and strict success. Fable 5.1 scores 77.9% with partial credit but 41.7% under the strict criterion. The first score rewards steps completed within a workflow; the second requires more complete success. Anthropic also notes that the August 2026 tasks are not directly comparable with earlier versions of the benchmark.[1]
CursorBench adds an external signal to Anthropic’s table, since Cursor reports 73.4% at maximum effort. The benchmark nonetheless relies on tasks and an environment specific to Cursor. It sheds light on interactive coding, not on software engineering as a whole, production maintenance or the safety of code changes.[7]
Safeguards create their own governance problem
Tiered access addresses a real dilemma. Protection that is too broad blocks legitimate defensive or scientific work. Uncontrolled openness lowers the barriers to offensive uses. Anthropic has chosen to vet certain organizations and make Mythos more permissive within their domain. This solution shifts part of the problem to program governance: admission criteria, duration of authorization, usage monitoring, incident handling and revocation.
Verifying an identity or an affiliation is not enough to establish the purpose of a request. An approved organization can be compromised, an account can be hijacked, and a seemingly defensive request can serve an offensive operation. Trusted access programs must therefore combine identity, tool controls, usage limits, behavioral monitoring and action audits. The level of privilege should remain proportionate to the task rather than become a permanent right.
Anthropic says it has not identified any critical-severity cyber jailbreak in its internal and external testing. This wording does not mean a bypass is impossible. It describes the outcome of a set of tests at a given date. The company also acknowledges that Mythos 5.1 can sometimes circumvent approvals or auto-mode classifiers, and that its audits provide weaker coverage of very long contexts and multi-agent environments.[1][3]
EFS raises another question of accountability. Storing data on the customer side reduces data exposure to Anthropic and makes it easier to comply with strict internal policies. In return, the customer organization takes on a more visible share of the review, log retention and alert response. The confidentiality promise must therefore be assessed in light of the full architecture, the people authorized to access the data and the customer’s actual ability to handle incidents.[5]
Legal obligations remain tied to use
In the European Union, obligations for providers of general-purpose AI models have been in force since August 2, 2025. They cover, among other things, technical documentation, information for downstream providers, a copyright compliance policy and the publication of a summary of training content. Additional requirements apply to models classified as posing systemic risk, including risk assessment, incident reporting and cybersecurity. The AI Office and national authorities began enforcing and overseeing the regulation on August 2, 2026.[8]
These rules are not enough to determine the legal status of every deployment of Fable 5.1 or Mythos 5.1. Regulatory status depends on the actor’s role, the model involved and the system into which it is integrated. Anthropic’s publications on its own risk levels do not amount to a classification decision by a European authority. A deployer must therefore analyze its concrete use case, its data, the people affected and the decisions to which the agent contributes.
The GDPR continues to apply whenever an agent processes personal data. Reduced retention on the vendor side does not relieve the customer company of the need to define a purpose, a legal basis, a retention period, access rights and security measures. If a system alone makes a decision that produces a legal effect or significantly affects a person, the restrictions on fully automated decision-making must also be examined. Human oversight must then be real and capable of changing the outcome, not merely formal.[9][10]
What to watch next
The first question concerns the real effectiveness of differentiated safeguards. False positives, bypasses, reported incidents and the way Anthropic revises request categories will all need to be tracked. Fewer interventions are useful if they improve access for legitimate uses without increasing dangerous responses. The refusal rate alone cannot verify that balance.
The second question concerns access. The criteria applied to the cyber and life sciences programs will need to be precise enough to reduce risk, yet transparent enough to limit arbitrary decisions and disparities between large organizations, independent researchers and countries. The announced expansion beyond the United States will be an important test of this governance.
The third question is operational. Companies will need to measure full success rates, cost per task, human rework, permission-related incidents and log quality. Benchmarks show that Fable 5.1 is improving, but they also reveal gaps between partial and strict success, as well as the influence of routing to other models.
Fable 5.1 and Mythos 5.1 thus offer a concrete response to the spread of dual-use capabilities: a single model can be offered with different rights and protections. The reach of this approach will depend less on the model’s label than on the quality of vetting, the ability to audit actions and the accountability assumed by the vendor, the customer and the user when the agent acts on a real system.
Further reading
To further explore frontier models, agentic AI and the mechanisms that govern their sensitive uses, check out these articles from the aivancity blog.
Sources
[1] Anthropic, September 1, 2026. Introducing Claude Fable 5.1 and Claude Mythos 5.1. View the source
[2] Anthropic Claude Platform Documentation, accessed September 29, 2026. Claude Fable 5.1 Overview and What Is New. View the documentation
[3] Anthropic, September 2026. Claude Fable 5.1 and Claude Mythos 5.1 System Card. View the System Card
[4] Anthropic, accessed September 29, 2026. Transparency Hub Model Report for Fable 5.1 and Mythos 5.1. View the report
[5] Anthropic, September 1, 2026. Developing Enterprise Frontier Safeguards with Our Customers. View the source
[6] Zapier, accessed September 29, 2026. AutomationBench AI Agent Benchmarks. View the benchmark
[7] Cursor, accessed September 29, 2026. CursorBench. View the benchmark
[8] European Commission, updated 2026. General-Purpose AI Obligations under the AI Act. View the official fact sheet
[9] European Commission, accessed September 29, 2026. Restrictions on the Use of Automated Decision-Making. View the official source
[10] CNIL, updated 2026. Développement des systèmes d’IA et recommandations pour respecter le RGPD. View the recommendations